Zentraix
Choosing a top H100 server manufacturer in China takes more than comparing product pages. Buyers need to examine the complete system: H100 GPU configuration, CPU and memory options, network adapters, cooling design, and power requirements. A server may look impressive in a brochure but still miss the needs of a particular training workload. Details matter.
This guide explains how to assess manufacturers and compare their offerings using practical criteria, not unsupported rankings. It considers product documentation, customization, integration capabilities, warranty terms, and the availability of technical support. Readers should confirm specifications directly with each supplier, since configurations and delivery conditions can change. An h100 server manufacturer should be able to explain its system design clearly, provide verifiable technical information, and discuss realistic deployment requirements. Claims about performance deserve careful checking; a headline number rarely tells the whole story. Even a tidy comparison has limits. The right choice depends on workload, budget, facility constraints, and support expectations. We will outline what to ask before shortlisting a vendor, so buyers can make a more informed decision without treating marketing language as proof.
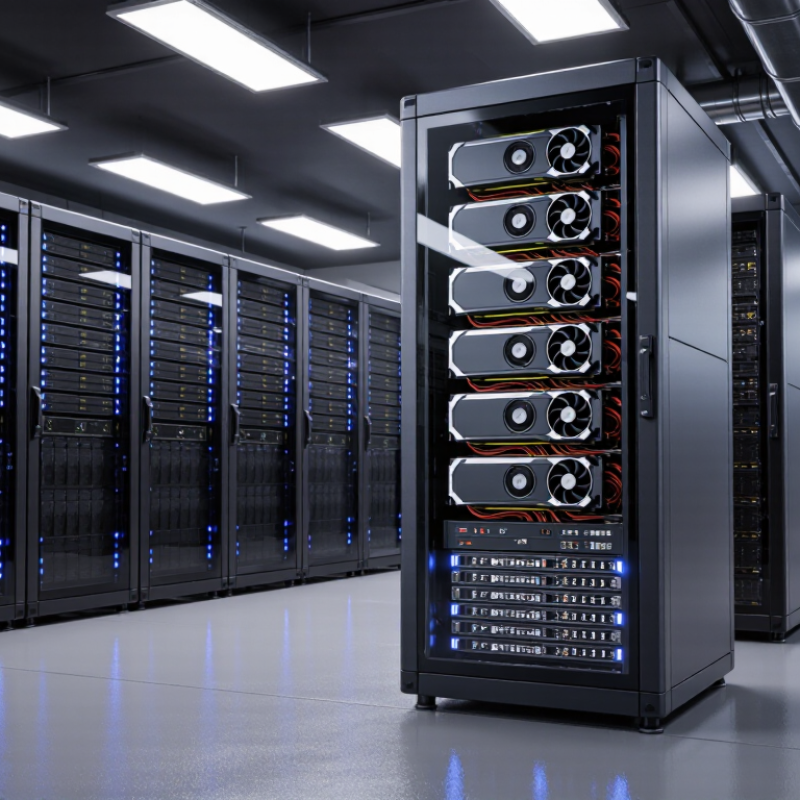
An H100 server in the Chinese market is more than a machine fitted with high-end accelerators. It is a complete system designed to keep intensive AI workloads running steadily. Buyers should examine the number and configuration of GPUs, CPU capacity, memory, storage, and network bandwidth. Cooling and power delivery matter just as much. A dense chassis may look impressive, but it must also handle sustained heat in the intended data-center environment.
Configurations vary by workload and supplier, so compare verified specifications rather than product labels alone. Check whether the server supports the required software stack, monitoring tools, and network connections. Ask for test results under realistic workloads, not only peak-performance figures. Service coverage and replacement-part availability also affect uptime. One detail is easy to overlook: a configuration that performs well in a short test may behave differently during continuous operation. The checklist can still miss something; validate the system on-site when possible.
Tips: Confirm GPU count, power draw, cooling method, and workload compatibility in writing. Request a clear acceptance test before purchase. Small checks matter.
When evaluating Chinese H100 server manufacturers, look beyond advertised GPU counts. Request a complete configuration sheet covering GPU interconnects, memory, CPU, storage, networking, and power requirements. A rack drawing can reveal whether the system fits your facility and airflow plan. Numbers are not enough.
Ask for evidence from realistic workload testing, not only peak-performance claims. Useful records include sustained throughput, GPU utilization, thermal readings, and behavior under long training runs. Check how the manufacturer validates cooling and power delivery at your intended operating conditions. Ask for proof. If possible, review test reports and speak with customers who run comparable workloads.
Assess engineering support as carefully as hardware. Clarify response times, spare-parts availability, firmware maintenance, and the process for diagnosing failures. Confirm that documentation covers installation, monitoring, and safe servicing. Compare delivery schedules and warranty terms in writing. A low quote may omit integration work or support that matters later. I would not choose from a specification sheet alone; it is easy to miss practical constraints. Still, even a factory visit cannot predict every issue. Use a pilot deployment to check performance, noise, heat, and service workflows before committing to a larger order.
China’s H100 server market is easier to assess by supplier capability than by a simple ranking. Large system manufacturers generally offer rack integration, production capacity, and established service networks. Design-focused suppliers may provide more flexible configurations, while specialist integrators often concentrate on cooling, high-speed networking, and deployment support. The differences show up in the details.
IDC’s Worldwide Quarterly Server Tracker reported that global server revenue rose 91.8% year over year in the fourth quarter of 2024, reaching $77.3 billion. That growth signals strong demand for accelerated computing, but it does not confirm any individual supplier’s H100 availability or delivery record. Buyers should request configuration-specific validation, not rely on market momentum.
Power and cooling deserve equal scrutiny. The International Energy Agency’s Electricity 2024 report estimated that data centres, AI, and cryptocurrency used about 460 terawatt-hours of electricity in 2022, with demand potentially exceeding 1,000 terawatt-hours by 2026. For an H100 rack, ask for measured power draw under sustained load, cooling requirements, firmware support, spare-parts lead times, and acceptance-test results. A polished datasheet is not enough. And supplier claims still need checking; that part is easy to overlook.
H100 servers from Chinese manufacturers may use the same accelerator, yet their configurations can differ sharply. Common choices include four or eight GPUs, different CPU and memory capacities, and varied high-speed interconnect layouts. The H100 technical brief lists 80 GB of HBM3 memory; its SXM version can draw up to 700 watts, compared with 350 watts for the PCIe version. These figures make chassis design and cooling capacity practical points of comparison.
An eight-GPU system needs more than eight accelerator slots. Buyers should check power-supply headroom, airflow direction, network bandwidth, and whether all GPUs can sustain performance under heavy workloads. Uptime Institute’s 2024 Global Data Center Survey highlights power availability and cooling as ongoing data-center constraints. That context matters: a dense server may look efficient on paper, but demand careful facility planning. Spec sheets can still hide trade-offs.
Tips: Compare sustained power and cooling requirements, not just peak GPU counts. Ask for workload test results and rack-level power figures. Small omissions matter. H100 technical figures: 2024 H100 platform technical brief; facility context: Uptime Institute, 2024 Global Data Center Survey.
H100 servers are commonly used to train large language and vision models, where multiple GPUs process batches of data in parallel. They also support inference, scientific computing, and engineering simulations that need substantial GPU memory and fast data movement. In a practical deployment, the workload may involve streaming datasets from shared storage while GPUs exchange model data across high-speed links. Latency matters. So does sustained performance under load.
Selection starts with the workload, not the GPU count. Check memory capacity, interconnect design, CPU balance, and network bandwidth against actual training or inference needs. Then examine power draw, rack space, cooling requirements, and noise. A dense system can generate significant heat; the server room must handle it continuously, not just during a short test. Ask for workload-based benchmarks and verify support for the intended software stack. I would not treat a single benchmark as proof of fit. Results can change with data, model size, and configuration, and that uncertainty deserves a closer look. Test representative jobs before committing to a full deployment.
H100 PCIe and SXM GPUs offer 80 GB of memory per GPU, while H100 NVL offers 94 GB. Memory capacity is one factor when sizing servers for large language model training and inference; also consider GPU count, power and cooling, and high-speed interconnects.
Request a full configuration sheet. Check interconnects, memory, processors, storage, networking, and power needs. Numbers are not enough.
It shows whether the system fits your room and airflow plan. Check rack dimensions before delivery.
Ask for sustained throughput, GPU utilization, and thermal readings during long training runs. Peak performance alone can mislead.
Request measured power use under sustained load and cooling requirements for your intended conditions. Ask for acceptance-test results, too.
Get written response times, spare-parts lead times, and firmware maintenance plans. Check how failures are diagnosed.
Look for installation, monitoring, and safe servicing instructions. Missing details can slow a repair.
Compare delivery schedules and warranty terms in writing. A low quote may leave out integration work or ongoing support.
Not quite. A visit cannot reveal every issue. Run a pilot and check performance, noise, heat, and service workflows. I might still miss something.
An H100 server is a high-performance computing system built around NVIDIA H100 accelerators, with its design shaped by factors such as GPU count, processor and memory capacity, networking, cooling, and power requirements. In China’s market, configurations can vary considerably, so comparing systems involves more than counting GPUs. Buyers should assess workload fit, expansion options, system integration, reliability, technical support, and the clarity of configuration and service terms when evaluating an h100 server manufacturer.
Leading manufacturers may offer different approaches to server architecture, from compact configurations to larger systems designed for demanding parallel workloads. These servers can support applications such as AI model training and inference, scientific computing, and data analysis. The right choice depends on performance needs, infrastructure compatibility, operating costs, and the level of support required. A careful comparison of specifications and deployment requirements helps organizations select a configuration suited to their intended use.