Zentraix Zentraix

2026 Best NVIDIA GPU Server Manufacturers for AI Workloads

Time:2026-11-08 Author:Sienna
0%

Choosing a server for AI is not just a GPU-count exercise. A well-matched system balances accelerators, memory, networking, power delivery, cooling, and software support. The right balance depends on the workload. Training large models can stress high-speed interconnects, while inference may depend more on memory capacity, latency, and operating cost.

NVIDIA CEO Jensen Huang once joked, “The more you buy, the more you save.” The line is playful, not purchasing advice. Still, it points to a real question: what does each server deliver over its useful life? A credible nvidia gpu server manufacturer should provide clear configuration details, validated performance data, service terms, and practical guidance on deployment. Look beyond peak GPU specifications. Check the complete system.

This guide compares manufacturers for AI workloads in 2026, focusing on architecture, scalability, cooling, manageability, and support. It also considers how systems fit different environments, from compact inference deployments to large training clusters. Specifications matter. So does implementation. Vendor benchmarks can help, but they may not reflect your model, data pipeline, or facility limits. Treat comparisons as a starting point, not a verdict. Real-world results can be less tidy. That deserves attention.
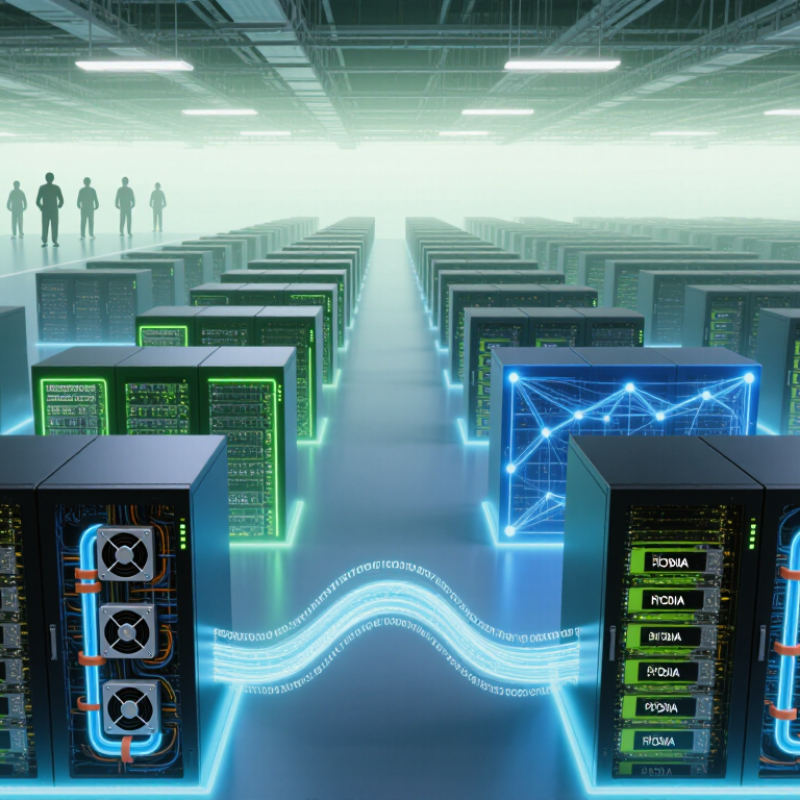
2026 Best NVIDIA GPU Server Manufacturers for AI Workloads

What Defines an NVIDIA GPU Server for AI Workloads

An NVIDIA GPU server for AI workloads is not defined by accelerator count alone. It is a balanced system in which GPUs, CPUs, memory, networking, storage, and cooling work together. A model can stall when data arrives too slowly, even if expensive accelerators sit inside the chassis. Look for high-bandwidth links between GPUs, enough memory for the intended model, and fast storage for training data and checkpoints. Balance matters more.

Power and thermals are equally important. The International Energy Agency’s Energy and AI report estimates that data centres used about 415 TWh of electricity worldwide in 2024; demand could more than double by 2030. That makes power delivery, cooling capacity, and sustained performance practical selection criteria, not afterthoughts. Ask for workload-based testing under steady thermal conditions, plus service details for replacing fans, drives, and power supplies. A polished specification sheet can still hide a weak cooling design. Real installations are messier than the brochure suggests.

Tips: Match server configuration to model size and workload. Check GPU utilization, temperatures, and power draw during a representative run. Don’t assume peak benchmark speed predicts daily results.

How AI Workloads Shape GPU Server Requirements

AI workloads place different demands on a GPU server. Model training may keep accelerators busy for days, while inference can bring sharp, unpredictable traffic spikes. Both need adequate GPU memory, but memory capacity alone is not enough. Data must move quickly between GPUs, processors, storage, and network interfaces. Slow links can leave expensive accelerators waiting.

Heat is real. Dense configurations need carefully designed airflow or liquid cooling, plus power delivery that can sustain prolonged loads. A system that performs well during a brief test may throttle after hours of computation. Measure temperatures, power draw, and throughput under realistic conditions. Noise matters too.

When comparing manufacturers, examine server layouts, supported GPU configurations, expansion options, and service procedures. Ask how the system behaves when one fan, drive, or power supply needs attention. Request workload-relevant testing, not just peak performance figures. Logs and repeatable benchmarks make comparisons more dependable. A spreadsheet can miss this. Some sizing decisions remain imperfect because models, software, and traffic change. Leave room for growth, but avoid paying for capacity your workload may never use.

How AI Workloads Shape GPU Server Requirements

Floating-point formats used in AI workloads differ in their storage width, influencing memory use and the precision available for computation.

What it means: Lower-bit formats use fewer bits per value, which can reduce data movement and memory requirements. The appropriate format depends on workload accuracy needs and hardware and software support.

Criteria for Evaluating NVIDIA GPU Server Manufacturers

Choosing a GPU server manufacturer starts with workload fit, not a peak-performance figure. Ask how many accelerators the chassis supports and whether they can sustain power under continuous use. A dense system may look efficient on paper, yet restricted airflow can cause throttling during long training runs. Request thermal test results at realistic room temperatures, not only ideal lab conditions.

Check the full platform. The server should provide adequate CPU lanes, memory capacity, and fast networking for the intended data pipeline. Confirm that power supplies, cooling components, and firmware are designed for the specified accelerator configuration. Ask for clear documentation on driver validation, operating-system support, and maintenance procedures. Short answers are not enough.

Service matters. Find out how quickly replacement parts can reach your site and whether technicians can diagnose faults remotely. Request references from organizations with similar workloads, then ask what failed and how long recovery took. A polished demo proves little. Compare warranty terms, spare-part availability, and support response targets in writing. Some details will remain uncertain until the system is installed; that is a real evaluation gap, not a reason to skip testing. Run a representative workload before expanding deployment.

Leading NVIDIA GPU Server Manufacturers in 2026

In 2026, leading GPU server manufacturers will stand out through more than accelerator counts. Look for validated multi-GPU systems, stable high-speed connections, and power designs that sustain demanding workloads. A dense server may fit eight accelerators into one chassis, yet poor airflow can throttle performance. Thermals matter.

IDC’s 2024 Worldwide AI and Generative AI Spending Guide projects global AI spending will reach $632 billion by 2028, growing at a 29% compound annual rate from 2023. That growth makes dependable supply, clear warranty terms, and accessible replacement parts important selection criteria. The IEA’s Electricity 2024 report estimates that data centres, AI, and cryptocurrency together used 460 TWh in 2022; demand could reach 620–1,050 TWh in 2026. This makes measured power efficiency and cooling support practical buying factors. A specification sheet can still mislead: peak capacity does not prove sustained performance. I would challenge any shortlist that lacks workload-based thermal and power test results.

Tips: Ask for sustained-load test data, not just peak benchmarks. Confirm rack power, cooling requirements, firmware support, and service response times before ordering.

How to Match a Manufacturer to Your AI Deployment Needs

Start with the workload, not the rack quote. A team training large models may need several GPUs linked by fast interconnects, while an inference service may prioritize memory capacity and predictable latency. Ask each manufacturer to map its proposed server to your model size, data format, and expected user load. Request measured results, not peak-performance figures alone. Small tests matter.

Check the details that affect daily operation: power draw under sustained load, cooling requirements, network bandwidth, and access for replacing a failed component. A server that fits the room but overwhelms its cooling system is not a good match. Ask whether the manufacturer can validate your software stack before delivery, and what response times its support team can realistically provide. That gap hurts.

Compare deployment timelines and upgrade paths, too. Confirm which components can be changed without replacing the whole system, and whether spare parts are available where your team operates. For a small pilot, a modular system may reduce risk; for a larger cluster, consistent configurations can simplify maintenance. One awkward reality remains: requirements often shift after testing. Share your assumptions, then ask the manufacturer to identify the trade-offs they would revisit as usage grows.

FAQS

Why do training and inference need different server planning?

Training may keep accelerators busy for days. Inference can create sudden traffic spikes. Plan for both patterns.

Is GPU memory capacity enough for good performance?

No. Data also needs fast paths between GPUs, processors, storage, and network interfaces. Slow links can leave accelerators idle.

How can I check whether cooling is adequate?

Test the server under sustained workloads, not just brief demos. Track temperatures, power draw, and throughput. Noise matters too.

What should I check in a dense GPU configuration?

Confirm supported accelerator layouts, power delivery, and airflow. A crowded chassis may throttle during long training runs. Lab results can be imperfect.

Which platform details affect data-heavy workloads?

Check CPU lanes, system memory, and network speed. Make sure the full data pipeline can feed the accelerators.

What testing should a manufacturer provide?

Ask for repeatable benchmarks using a workload like yours. Review logs and realistic thermal results. Peak figures alone tell little.

How should I evaluate service and repairs?

Ask how replacement parts reach your site and whether faults can be diagnosed remotely. Check written response targets and maintenance steps.

How much room should I leave for future growth?

Allow for changing models and traffic, but avoid unused capacity. Some estimates will be wrong. Reassess after real workloads run.

Conclusion

This article explains what distinguishes an NVIDIA GPU server designed for AI workloads, including its accelerators, memory capacity, high-speed interconnects, cooling, and software compatibility. It explores how training, inference, and data-intensive applications place different demands on computing density, scalability, reliability, and power efficiency. These requirements provide a practical foundation for assessing server solutions in 2026.

The guide also outlines how to evaluate a nvidia gpu server manufacturer by considering system performance, configuration flexibility, support, integration capabilities, and long-term operating needs. Rather than treating one design as suitable for every organization, it shows how to compare manufacturers and match a solution to deployment scale, workload type, infrastructure, budget, and future growth plans.
Sienna

Sienna

Sienna is a skilled marketing professional with a deep expertise in our company’s core products and services. With a passion for innovation and detail, she plays a pivotal role in crafting insightful blog posts that not only highlight the unique features of our offerings but also provide valuable......